Lecture 3: Bellman Optimality Equation
强化学习中的数学原理 | 第三课

这次课会学习最优策略(Optimal Policy)和贝尔曼最优公式(Bellman Optimality Equation)
核心:最优策略的定义以及怎么寻找最优策略
首先确保理解了state value和action value的计算
Question: while the policy is not good, how can we improve it?
我们可以更新policy,让
正确性?
这个找到最优policy的方式,他的正确性其实并不那么直观
如果policy一坨屎,拿屎迭代真的还能迭代出好的policy吗?
下面我们将从数学上证明,只要不断迭代,最后一定得到的是最优的策略。
使用到贝尔曼最优公式(Bellman Optimality Equation)
we know that the state value could be used to evaluate if a policy is good or not:
if
then
A policy
To answer these questions, we study the Bellman optimality equation.
相比于贝尔曼公式就在前面多了一个
Remarks:
are known are unknown to be calculated is unknown. 在贝尔曼公式中 是给定的,但在贝尔曼最优公式中是待求解的
Bellman optimality equation (matrix-vector form):
BOE is tricky yet elegant!
- elegant: it describes the optimal policy and optimal state value in an elegant way.
- tricky: there is a maximization(最优化问题) on the rhs,which may not be straightforward to see how to compute.
Many questions to answer:
- Algorithm: how to solve this equation?
- Existence: does this equation have solutions?
- Uniqueness: is the solution to this equation unique?
- Optimality: how is it related to optimal policy?
BOE: elementwise form
BOE: matrix-vector form
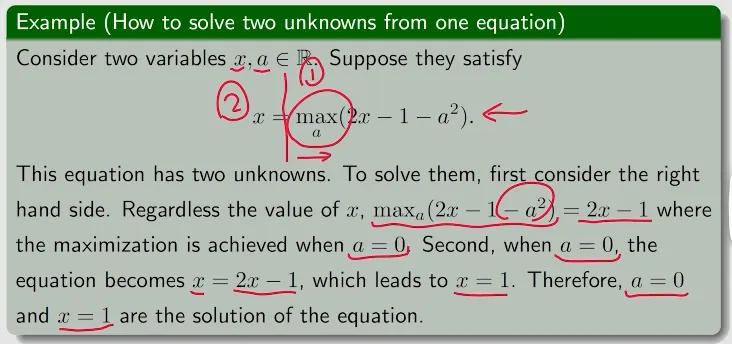
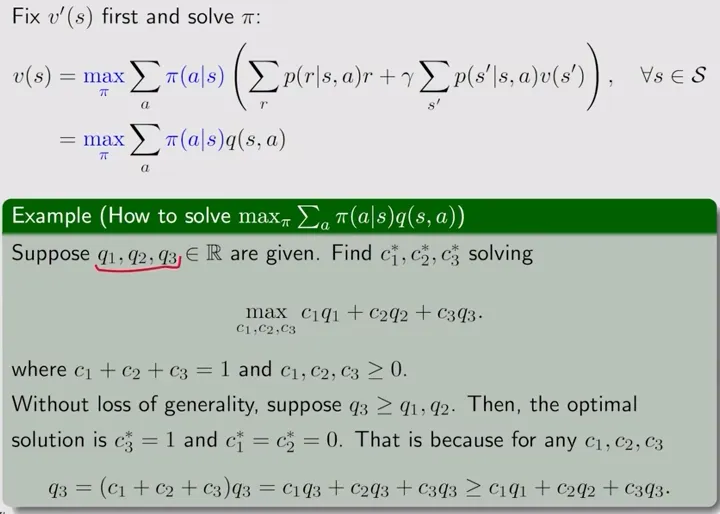
这个最优化问题就是上面例子里的每一项的系数和为1的一个问题
从上面的例子我们就能发现,由于
where the optimality is achieved when
where
The BOE is
then, the Bellman optimality equation becomes
where
some concepts:
Fixed point 不动点:is a fixed point of if
- Contraction mapping (or contractive function):
is a contraction mapping if
where
严格小于1, can be any vector norm
然后我们就可以看看压缩映射原理
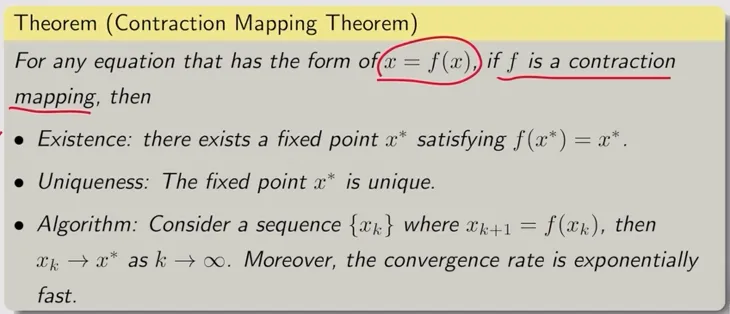
where
证明在书上,大致是注意到
Applying the contraction mapping theorem gives the following results.
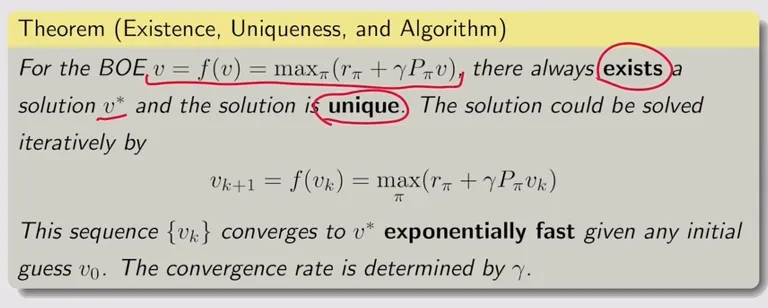
Suppose
Suppose
Then
Therefore,
Is
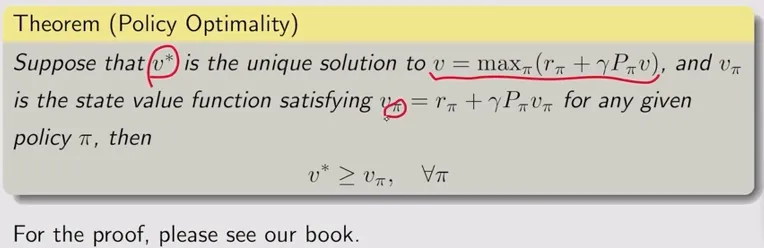
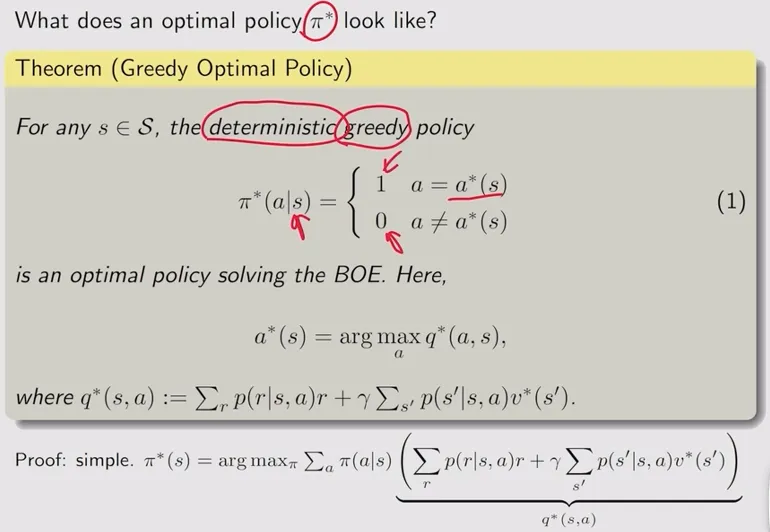
上面已经介绍完了贝尔曼最优公式,下面我们用他来分析一些最优策略
公式里哪些因素影响了最优策略呢?
可以看到公式里红色就是已知的的概率、reward、
there are three factors:
- Reward design:
- System model:
代表了系统的模型 - Discount rate:
are unknowns to be calculated
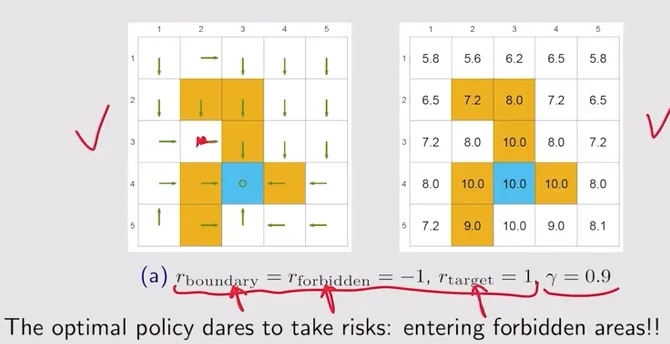
我们将通过例子看一下改变
- 如果
中惩罚设置不那么高的话,策略会敢于尝试take risks
变小会导致最优策略变得shorted-sighted
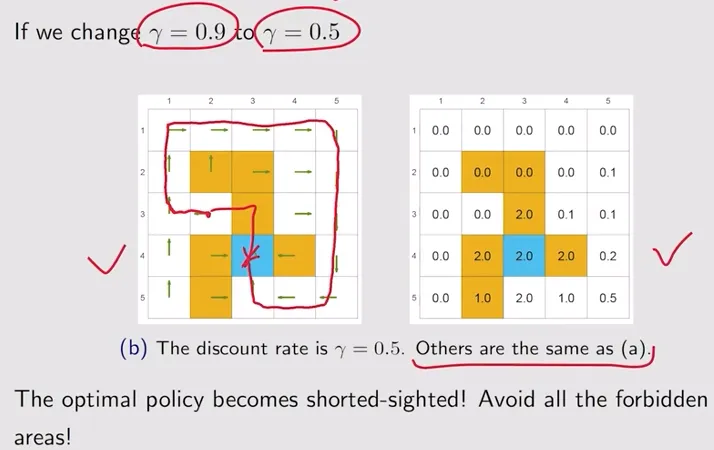
- What if we change
?
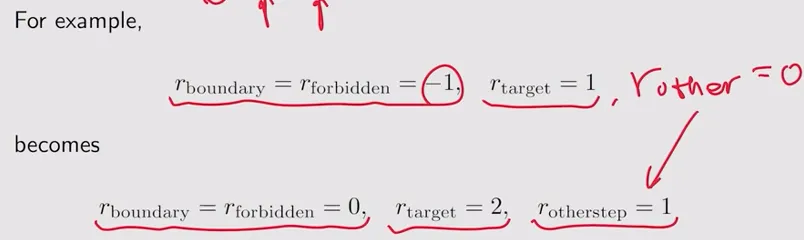
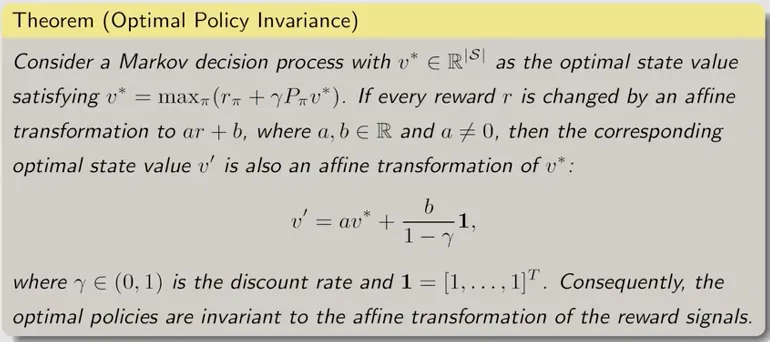
对整体 r 表做线性变换,实际可以发现不会对最优策略产生影响
What matters is not the absulate reward values! It is their relative values! 因为我们选择的时候只关注最大的,不关注有多大
严谨公式:
- Meaningless detour. 不需要给无意义的一步特地加上惩罚
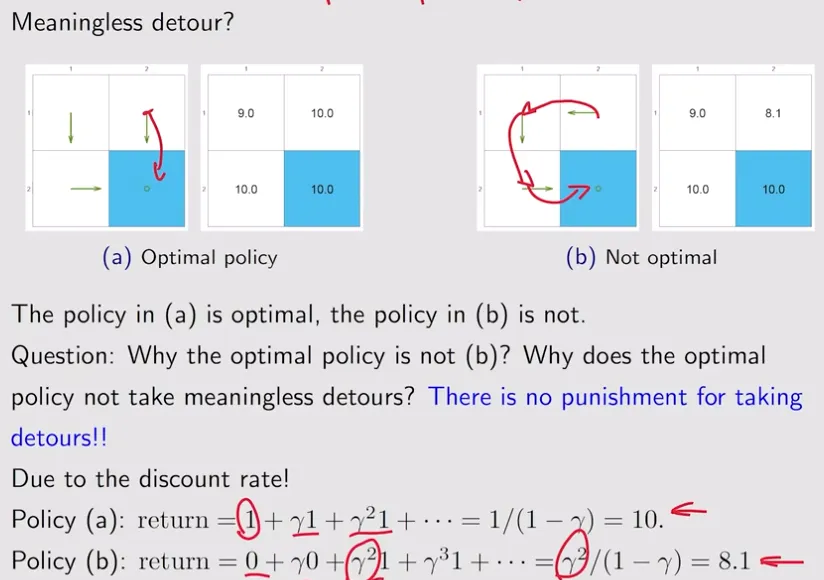
discount rate会起到不让他绕远路,而是尽快拿到奖励的作用
- BOE 一定有解,且根据压缩映射原理解一定是唯一的(最优的
是唯一的, 不一定唯一) - 我们给出了 iterative algorithm 来求解最优解
结束了 BOE,keep learning